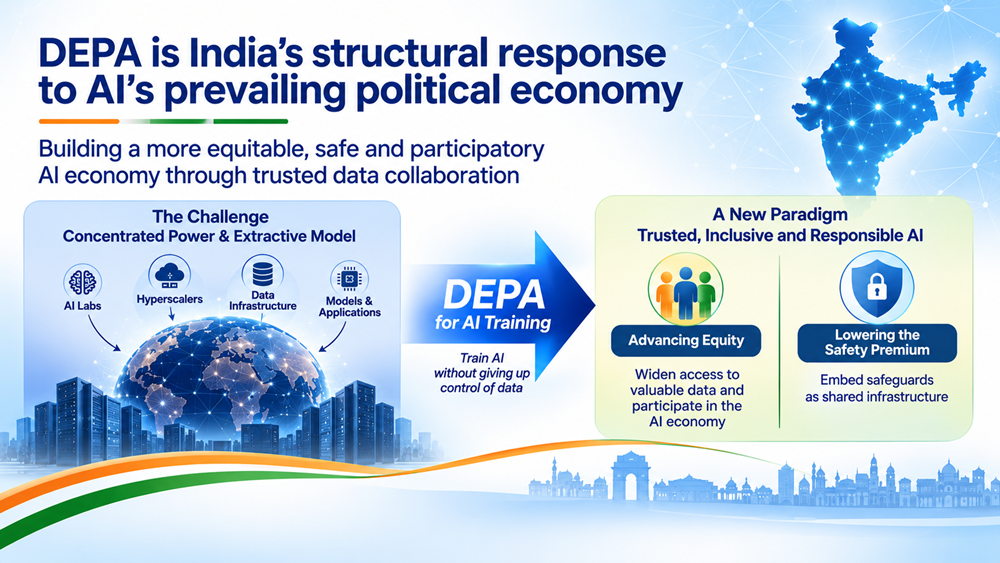
DEPA is India’s structural response to AI’s prevailing political economy

The prevailing political economy of AI development and use is characterised by highly concentrated power and extractive economic models. By making access to valuable data and its responsible use for AI development less dependent on the scale and bargaining power of a handful of dominant market players, India is beginning to reshape who gets to participate in the AI economy, on what terms, and who benefits. The recent launch of DEPA for AI Training Handbook by the Ministry of Electronics and Information Technology marks India’s concrete step towards laying the foundations for a more equitable, safe and participatory AI economy.


The global artificial intelligence (AI) economy is taking shape around an unprecedented concentration of capabilities. A handful of frontier AI labs, hyperscalars, and advanced economies exercise disproportionate control over critical layers of the AI value chain, spanning energy, compute, data infrastructure, models and applications. This concentration is shaping not only who develops AI, but also who captures its economic value and sets the terms of participation, often through extractive models of value creation. This presents a fundamental political economy challenge. At its core, among other questions, is who controls and can access the data needed to develop AI.

Much of the high-value data needed to develop contextually relevant AI resides with hospitals, banks, universities, businesses and public institutions. Yet existing arrangements for accessing and using it often require institutions to risk compromising control over sensitive information, navigate cumbersome and expensive bilateral agreements or forgo participation altogether. At the same time, rising expectations around the enforcement of privacy, data rights and accountability in AI development and use are placing greater demands on AI developers—not that this is undesirable; these safeguards are crucial. However, the infrastructure and expertise needed to meet these expectations remain concentrated among well-resourced incumbents, potentially turning safety into another barrier to entry and reinforcing their unfair advantage.

The challenge is therefore to democratise the conditions for AI participation: making critical inputs accessible, enabling adaptation to local needs and embedding safeguards without concentrating control or imposing prohibitive costs on new market entrants.

Reimagining the economics of data access

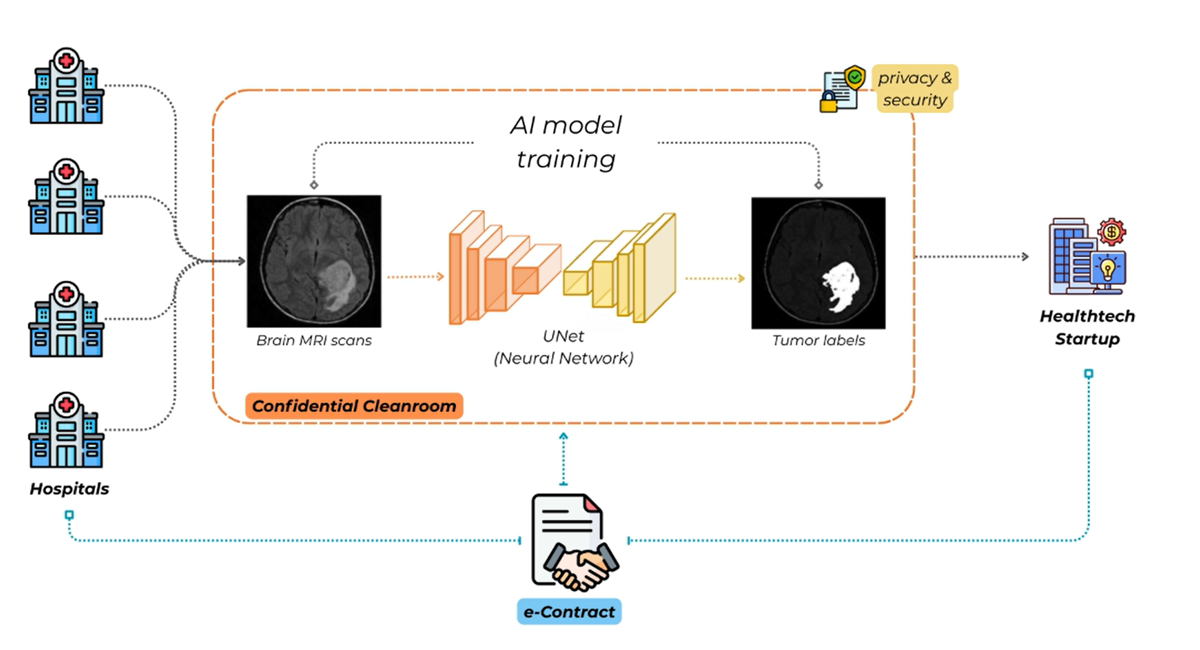
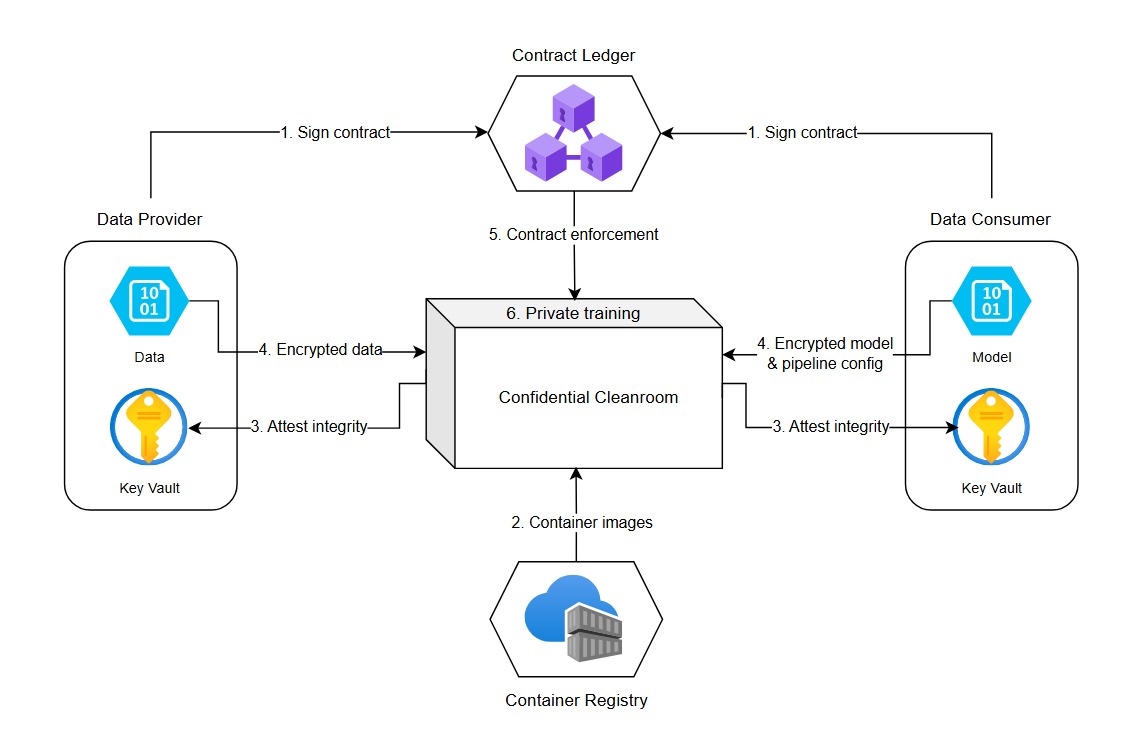
India’s Data Empowerment and Protection Architecture (DEPA) for AI Training is a structural intervention in the prevailing political economy of AI. It seeks to decouple access to valuable institutional data for AI training from the need to surrender control over it. Rather than requiring institutions to transfer their underlying datasets, DEPA for AI Training enables models to be trained where the data resides. Confidential clean rooms, privacy-enhancing technologies such as differential privacy, machine-enforceable contracts and auditable records provide the safeguards to make this possible. Multiple institutions, both within and across borders, can therefore collaborate on training models within controlled environments without exposing or relinquishing custody of their respective datasets. 

This changes the economics of AI participation in two important ways:

First, it advances equity by widening access to the inputs needed to build AI. Valuable institutional datasets become usable without data owners relinquishing privacy, confidentiality, or institutional control. Common infrastructure and reusable safeguards reduce the costs of trusted collaboration, enabling resource-constrained developers and researchers to access data and participate in AI innovation on a more equitable footing alongside established players. Traceable data use, attribution and appropriate economic arrangements can also allow data providers to participate more meaningfully in the value generated from their contributions. DEPA for AI Training thus begins to shift the data economy from extraction and concentrated control towards rights-respecting access and distributed participation.

Second, it lowers the premium on safety by making safeguards part of the shared infrastructure. As the universe of AI trust and safety requirements expand and become more demanding, the cost of independently developing and demonstrating trustworthy AI risks becoming another market barrier, disproportionately favouring well-resourced incumbents. By embedding safeguards for privacy, data rights and accountability into shared digital public infrastructure, DEPA for AI Training can reduce this burden and make responsible AI development more accessible. Safety thus becomes an enabler of wider participation rather than a market barrier that favours only those with the resources to meet its rising costs.

In summary, DEPA for AI Training has laid the foundations for a more inclusive political economy of AI—one that broadens access to data for beneficial AI innovation and local adaptation, preserves institutional control for data custodians and rights holders, and makes responsible AI development accessible beyond well-resourced incumbents.

Please note: The blog post is authored by Raj Shekhar, a volunteer with iSPIRT.
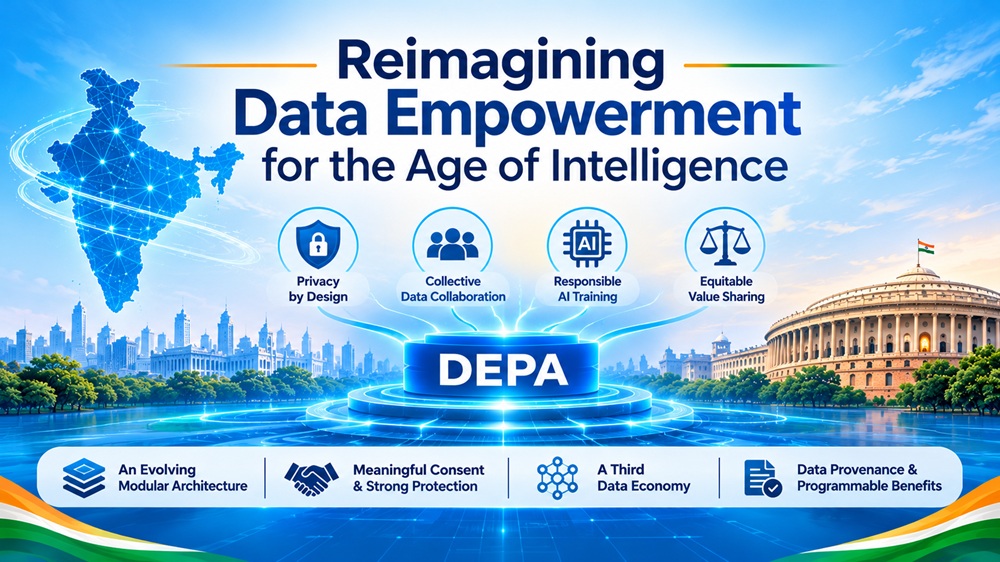
Reimagining Data Empowerment for the Age of Intelligence

The recent publication of the DEPA for AI Training Handbook has invited a necessary and rigorous public debate. Because the Handbook is explicitly a draft for discussion, this kind of sharp feedback is not just welcome, but essential for co-creation.

The debate raises two important questions: whether individual consent alone can adequately protect people in the context of AI training; and whether the presence of existing cryptographic primitives necessarily diminishes the architectural ingenuity of Digital Public Infrastructure (DPI).

An Evolvable, Modular Architecture

From its inception, DEPA was never conceived as a single product or a static specification. When iSPIRT first conceptualized DEPA in 2016, and NITI Aayog published the draft discussion paper in August 2020, it was explicitly framed as the final layer of India Stack—an evolving architectural philosophy aimed at resolving a singular paradox: How do we empower citizens and unlock the societal value of data without compromising privacy or concentrating market power?

Even the 2020 NITI Aayog paper anticipated going beyond consent, explicitly stating: “It goes without saying that consent alone cannot be the only backstop to prevent data misuse… Mechanisms that enable consent can exist on a spectrum.”

What launched in 2021 as the Account Aggregator (AA) rail was merely the first instantiation of DEPA—built using the primitives available at the time to solve for 1-to-1 retail data portability. Like previous digital public infrastructures, DEPA’s core mission of empowerment and protection remains invariant, even as its cryptographic primitives modularly expand to include Confidential Clean Rooms, Electronic Contracts, and Differential Privacy to solve for the age of AI.

This evolution can be understood through three complementary pathways: DEPA with consent, enabling individual data sharing through Account Aggregators; DEPA with informed consent, enabling privacy-preserving computation across institutional boundaries through Private Inferencing; and DEPA for AI Training, enabling collective data use for AI training. These pathways are complementary, not competing or sequential, and together support information flows at individual, institutional and industrial scales, while preserving Protection and enabling Empowerment.

The Genealogy and Limits of Digital Consent

“Notice and Choice” was designed for a 1-to-1 bilateral relationship where the user understands the exact deterministic outcome of sharing a record—such as porting a bank statement to secure a loan. Consent was always a means to an end; the primal goal is privacy itself.

When applied to modern machine learning, elevating individual consent above all other safeguards can lead to systemic failures. In 2004, the Canadian Stroke Network mandated that hospitals obtain individual, opt-in consent from every patient before their de-identified records could enter a national registry. Participation rates collapsed, and the resulting dataset was fatally skewed. In-hospital mortality among the “consented” patients was 6.9%; among the unconsented patients, it was 21.7%. By treating individual consent as the sole gateway to collective medical knowledge, the system produced a dataset that was scientifically blind to the very patients most at risk.

This illustrates a broader paradox: an over-reliance on individual consent can reduce empowerment to repeatedly clicking through consent requests without meaningful understanding or control, while excluding people from the benefits of collective data use. It can also introduce selection biases that leave vulnerable populations underrepresented. If India requires every rural clinic patient to execute a real-time retail portability flow before their de-identified clinical outcomes can inform a national oncology or tuberculosis model, its poorest citizens risk being statistically erased from the medical intelligence of the future. In trying to preserve individual agency through consent alone, we risk undermining it and defeating the larger objective of ensuring that individuals and communities can participate in and benefit from the data economy.

This does not mean that consent should be dispensed with where it is legally required. Rather, consent must be meaningful. Where the purposes of AI training are not clearly defined, or individuals lack meaningful and enforceable avenues to revoke consent and exercise their rights, consent risks becoming a procedural formality. This raises important questions about meaningful consent and informational autonomy under the Indian Digital Personal Data Protection Act, 2023 and the principles articulated in Puttaswamy (2017). What is right must be done even when it is difficult to implement.

More critically, consent is permission, not protection. Millions of users have clicked “I Agree” on platforms or signed up for workspace tools whose Terms of Service permitted AI training. Because neural networks are lossy compression systems, research has time and again proved that standard LLMs inadvertently memorize verbatim sequences from their training data. Through membership inference and divergence attacks, adversaries have extracted real names, phone numbers, and private medical discussions from models trained on “consented” data. Consent gave the AI lab legal immunity, while leaving the user with zero privacy.

This exposes the illusion of revocability. Under true data protection frameworks, consent must be revocable. You can seamlessly revoke access to a bank statement. However, once a neural network’s weights are updated via stochastic gradient descent, the mathematical influence of a single record is permanently diffused across billions of parameters. “Machine unlearning” remains an unsolved computer science problem without retraining the entire model from scratch at a cost of millions of dollars. 

The Novelty of the Data Economy

There also has been a mention of Finland’s Findata (2019), the UK’s NHS Secure Data Environments (2022), and the Penn Medicine Federated Learning project (2022) to argue that DEPA for Training lacks novelty.

But by this yardstick, no DPI in history is novel. Aadhaar did not invent biometrics; UPI did not invent QR codes or XML messaging. Every successful DPI is built on a triad: a market, a policy, and a technical architecture. The genius of DPI lies in protocolizing battle-tested primitives to solve market failures—collapsing the transaction costs of search, bilateral bargaining, and enforcement across an entire economy.

In fact, DEPA is not just a secure enclave. We agree that secure enclaves have existed for a really long time, but historical evidence shows that without an ecosystem protocol, seamless multi-party data collaboration and private inferencing simply have not happened at scale. A standalone clean room works when data is homogeneous and centrally held by a state monopoly, like the NHS. However, it completely breaks down for multi-party, cross-sectoral collaboration. If an agritech researcher wants to train a predictive model combining private insurance claims, localized crop yields, and real-time weather data, a singular enclave model fails. The data legally and technically cannot be pooled into one centralized repository.

Even successful federations, like the Penn Medicine brain tumor study (which achieved 99% accuracy), required 71 institutions to spend years negotiating bespoke legal agreements and custom IT integrations. In the private market today, cloud vendors are signing bespoke $200 million deals to run models inside proprietary clean rooms—locking data inside one vendor’s walled garden.

DEPA for Training turns Confidential Clean Rooms into an open, interoperable techno-legal rail. Any data provider can contract with any innovator using standardized machine-readable policies.

The novelty here is not necessarily in the individual components, but in their combination. A new drug can be novel even when its constituent ingredients are already known; the innovation lies in how those ingredients are combined and formulated. DEPA similarly brings established technical and institutional components together into a new interoperable architecture.

The Third Data Economy

Finally, a critique of AI architecture must answer who captures the downstream value. It has been argued that the Handbook overlooks Data Principals, benefiting only institutions and model builders.

This critique ignores the stark reality of today’s global AI economy. Right now, the market is bifurcated between two extractive structures: the free market model of bilateral data brokers, unlicensed web scraping, RL environment and synthetic annotation marketplaces (where annotators are paid pennies at the bottom of the value chain while foreign labs own the frontier models), and the China model of state-centralized pools. In both current structures, individual citizens receive absolutely zero downstream benefit from the intelligence their data helped create.

It also overlooks the institutional design laid out in the Handbook itself. Section 2.2 explicitly introduces Data Collaboratives. Historically, the marginal economic value of a single individual’s data point is near zero, making 1-to-1 monetization virtually impossible. However, by enabling data collabs individuals gain the collective bargaining power required to negotiate equitable terms with global AI labs while ensuring that individual privacy is not compromised. 

Most importantly, a Digital Public Infrastructure does not mandate a single, rigid business model; it builds the programmable rails that make equitable models technically possible for the first time.

DEPA proposes a third kind of data economy where true value is realized for individuals and institutions alike through three structural guarantees:

  1. Data never changes hands: Raw data stays with its fiduciaries or community cooperatives; the computation travels to the data inside an attested clean room.
  2. End-to-End Provenance: Every dataset card, contract signature, attestation log, and spent privacy budget is recorded on a verifiable ledger.
  3. Programmable Value Sharing: Because every training and inference run is cryptographically metered under an Electronic Contract, DEPA can build the exact rails required for ongoing royalties, per-use compensation, collaborative model ownership, and priority clinical access for the public hospitals and communities whose data powers the breakthroughs.

This is particularly important for recognising the collective value generated by individual contributions. Data Principals contribute data that can be pooled through Data Producers and Data Collaboratives to create a larger resource with economic value. Institutional arrangements can then provide a mechanism for attributing and sharing a proportionate part of that value with contributors.

When we unbundled payments with UPI and credit data with Account Aggregator, critics similarly argued that existing banking rails were sufficient or that the labels were imperfect. Yet protocols beat platforms every time. DEPA is not a departure from citizen empowerment—it is what empowerment looks like when we graduate from data governance to governance of intelligence.

India’s AI leadership needs data sovereignty by design

Artificial intelligence (AI) is poised to transform how governments make decisions, deliver public services and address complex policy challenges. But realising this potential requires more than access to powerful AI models. India must ensure that its government departments can harness AI without surrendering control over their data or the hard-won institutional intelligence accumulated over decades. 

This raises a fundamental question: how can a public institution use data to adopt AI while retaining control over how it is accessed, used and governed? The answer goes beyond where data is stored or whether an AI provider promises not to use it for model training without proper authorisation. It is a question of sovereignty: who sets the rules, how those rules are enforced, and whether compliance can be verified.

Data sovereignty goes beyond provider assurances and data residency

Leading AI providers have introduced policies for enterprise customers to address concerns around how their data is used. Providers offer enterprise customers options to determine where their data is stored, and in certain cases, where AI workloads are processed during training and inferencing. For instance, OpenAI offers eligible enterprise and API customers data residency in India. OpenAI also states that it does not use business and API customer data to train its models by default. Anthropic makes a similar commitment for its commercial products. Google and Microsoft also offer protections for enterprise data through specified services.

These assurances and offerings from AI providers are a start. However, a promise not to train on customer data, on its own, does not establish that every use of data can be independently verified or that contractual obligations are actually enforced through technical controls. Similarly, a guarantee of data residency, i.e., storing data within national borders does not, by itself, determine who can access it, where AI workloads involving it are processed during training and inferencing, or whether restrictions on its use are technically enforced. Crucially, data can be compromised even when no data-sharing violation has occurred. Access to individual records, sensitive data elements or system logs may be sufficient to expose information, without transferring datasets elsewhere or using them for model training.

Data sovereignty is ultimately about institutions retaining effective and meaningful control over their data—not merely determining where it resides or relying on the assurances of those who process it. This understanding matters particularly for governments. Public institutions hold sensitive citizen information, confidential administrative records, and data of strategic importance to national security and sovereign interests. They need more than assurances about how a model provider handles their data, where it is stored, or whether it remains within national borders. They need enforceable rules governing how their data can be used, with mechanisms to verify compliance and establish accountability when those rules are breached. This is where India’s Data Empowerment and Protection Architecture (DEPA) Private AI Training and Inferencing frameworks come into play.

From contractual promises to enforceable safeguards

DEPA Private AI Training and Inferencing frameworks embody India’s DPI-centric techno-legal approach to AI regulation, which binds legal obligations to technical controls, enabling institutions to develop and use AI without surrendering control over their data. Rather than relying solely on legal guarantees of appropriate use, the frameworks seek to establish technological safeguards that constrain the ability to misuse data in the first place. They achieve this by embedding governance into the architecture through:

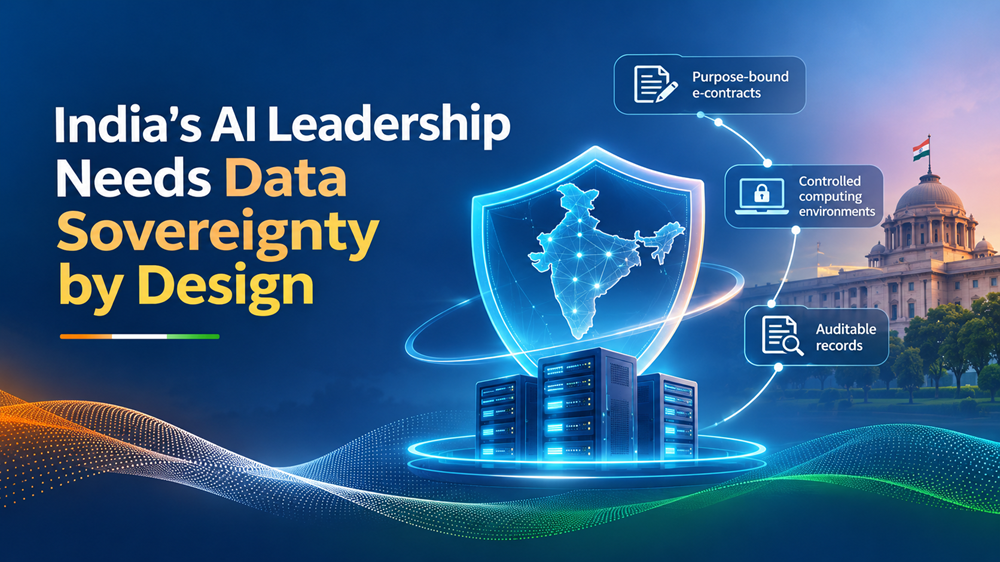
  • purpose-bound e-contracts that encode what data may be used, for what purposes and under what conditions;
  • controlled computing environments and privacy-enhancing safeguards that constrain how data is accessed and processed and reducing unnecessary exposure of sensitive information; and
  • auditable records that provide evidence of permissions, transactions and relevant decisions to support verification, oversight and accountability.

Together, these mechanisms provide a foundation for making compliance demonstrable and obligations enforceable by design. Their value lies in connecting legal rules to technical controls and records that can be examined by third-party auditors.

The way forward

The Indian government need not reject foreign AI providers or mandate that every AI system run on domestic hardware. It needs the capacity to choose, collaborate and compete without becoming dependent on any single provider’s infrastructure, policies, or rules. DEPA Private AI Training and Inferencing frameworks lay the groundwork for this vision. They are designed to enable institutions to unlock data for AI development with built-in safeguards for security, confidentiality, and accountability, ensuring effective and meaningful institutional control over data access and use.

India’s AI leadership will be determined not only by the models it builds, but also by whether it controls the infrastructure governing the data those models learn from. With this infrastructure now in place, the critical imperative is to operationalise it, enabling India to turn its strategic data assets into a source of enduring AI leadership without compromising its data sovereignty. This also means building the domestic knowledge and capabilities to independently operate and derive value from these assets, rather than relying on foreign actors. Building government personnel’s data and AI literacy will be essential to ensuring they can make informed decisions about data access and AI use.

Please note: The blog post is authored by Raj Shekhar, with inputs from Sunu Engineer, both volunteers with iSPIRT.

OCEN: Quarterly Performance

From Lending Infrastructure to an Ecosystem for MSME Growth

India’s Micro and Small Enterprises (MSEs) need timely working capital to buy inventory, pay suppliers, fulfil orders and sustain daily operations. Yet, many businesses remain underserved – not necessarily because they lack business activity, but because traditional lending models struggle to assess their creditworthiness and serve them economically.

The momentum is building

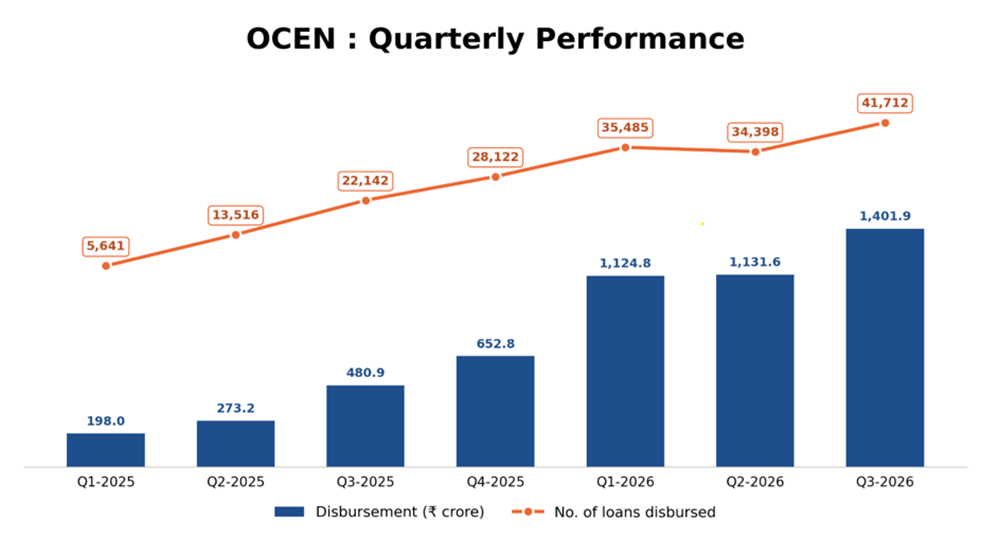
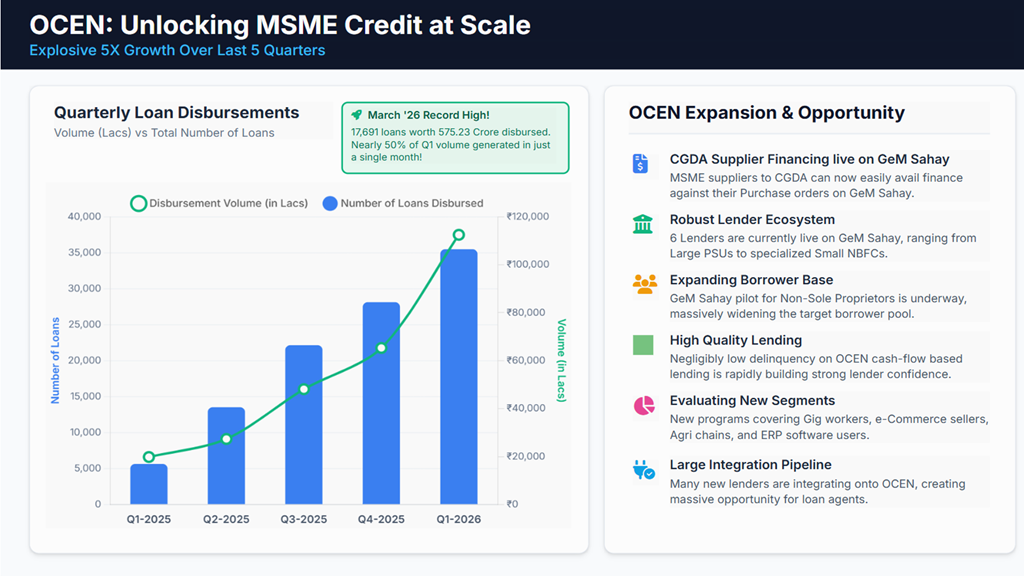
OCEN’s quarterly performance reflects growing momentum. Loan disbursements have increased from 5,641 loans worth ₹197.95 crore in Q1 2025 to 41,712 loans worth ₹1,401.91 crore in Q3 2026. This progress demonstrates the growing potential of digital lending programmes built on common infrastructure.

Beyond invoice financing

TReDS has established an important channel for financing eligible MSME trade receivables. However, businesses also need working capital for inventory, future orders, operating expenses and cash-flow gaps that may not be covered by eligible invoices.

This is where OCEN can complement existing financing channels. By enabling lenders to work with digital platforms and Loan Service Providers (LSPs), OCEN helps build pathways to serve businesses whose credit needs extend beyond invoice discounting.

Building an ecosystem around data-driven credit

OCEN is not a lender; it is an ecosystem builder. Through standardised digital interfaces, it enables lenders, LSPs and technology providers to collaborate, connect with borrowers and develop contextual lending products.

With appropriate consent and verification, business information- such as bank transactions, sales, collections and marketplace activity – can help lenders assess cash flows and repayment capacity. Data is not collateral in the legal sense, but it can strengthen credit assessment and help unlock lending opportunities for businesses with limited conventional collateral.

An opportunity for the entire ecosystem

Priority Sector Lending (PSL) requirements reinforce the policy objective of ensuring adequate credit reaches eligible MSMEs, including micro enterprises. Achieving this requires not just capital, but scalable distribution, better information and viable lending models.

Today, participants ranging from public sector banks to smaller NBFCs are live on OCEN, with more lenders working towards integration and scale. For lenders, this offers new distribution opportunities; for LSPs, access to participating credit providers; and for technology providers, the opportunity to build reusable services across the network.

TReDS demonstrated the potential of common infrastructure for invoice financing. OCEN is building on the broader opportunity to extend digital lending to MSMEs beyond that channel. Its journey today can be compared, in terms of ecosystem maturity, to where TReDS stood in 2019 – as a reminder of what sustained ecosystem participation can make possible.

The next chapter of MSME finance will be built through collaboration. OCEN provides the rails; lenders, LSPs and technology partners can turn them into meaningful credit access for millions of businesses.

For more information, please visit: https://ocen.dev

Please note: The blog post is authored by our volunteer, Rahul Bhaik

AIIMS Delhi and SolarWinds: When Trust in Digital Infrastructure Collapses

One was a 2 week ransomware siege that forced India’s top public hospital onto pen and paper. The other was a month-long espionage operation, hidden inside trusted software that went undetected across the US government and Fortune 500 companies until a security firm found it by accident. Most major breaches aren’t masterminds at work, they are ordinary, known risks such as an unpatched server, an unwatched build pipeline that became a crisis. AIIMS Delhi and SolarWinds show two different failures: one loud and aimed at a hospital, the other silent and aimed at the software supply chain everyone quietly depends on.

AIIMS Delhi (India, November 2022)

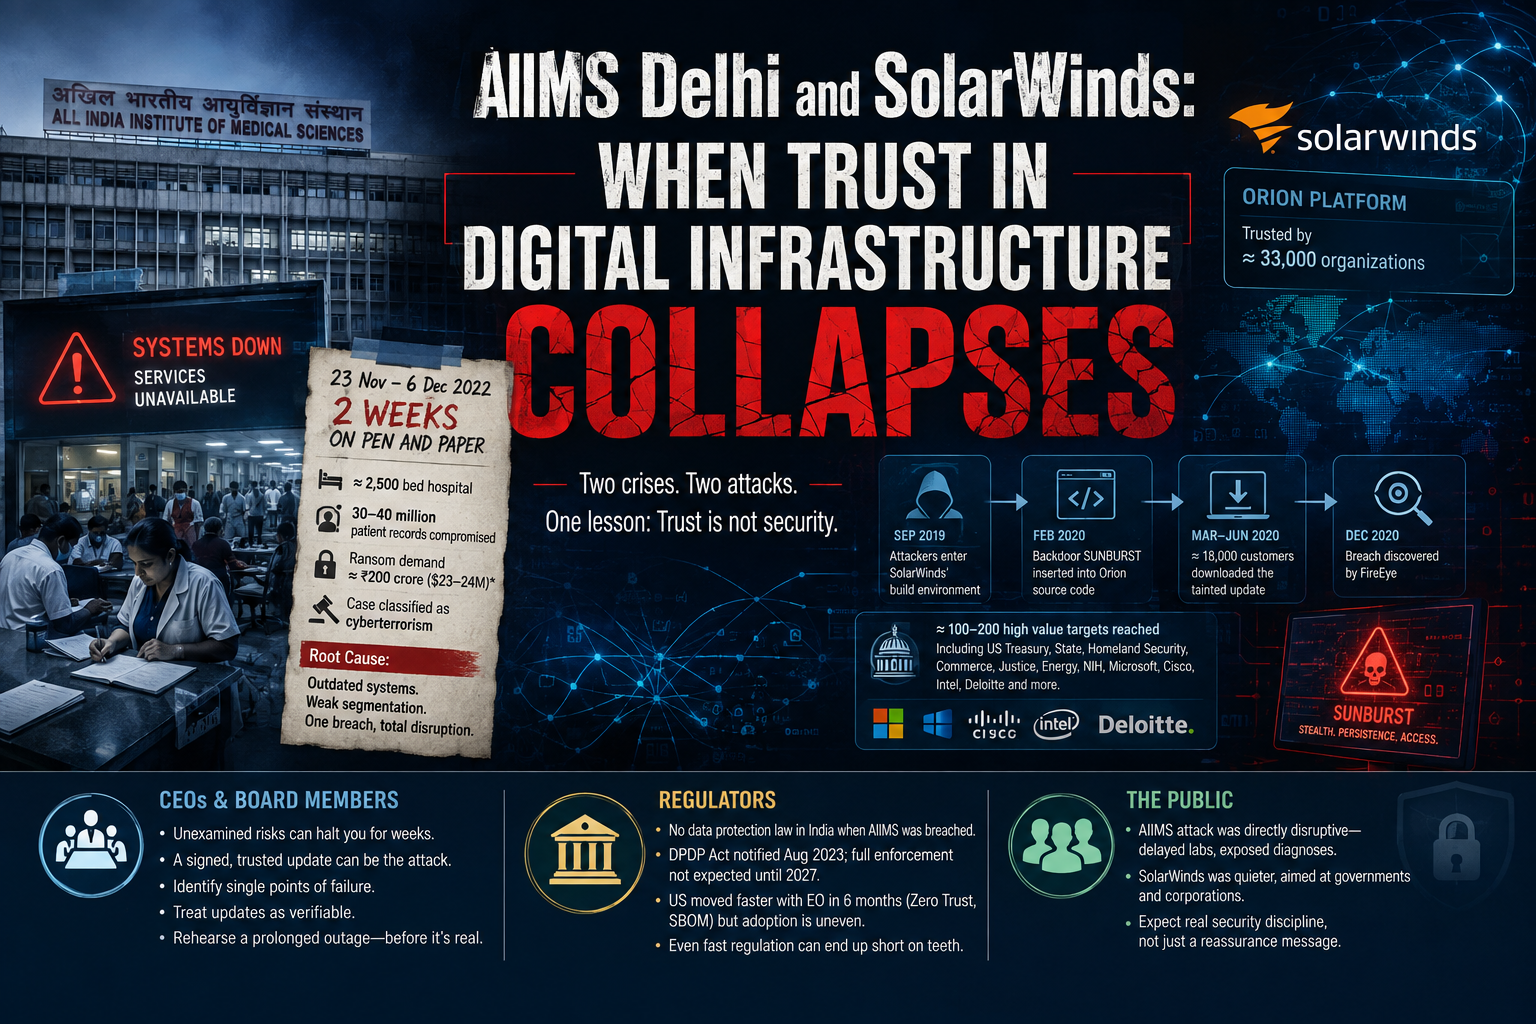
On 23rd November 2022, engineers managing servers at AIIMS New Delhi, a 2,500 bed public hospital, found 5 of roughly 100 servers compromised. The e-Hospital system running registration, admissions, billing and lab scheduling went dark. For nearly two weeks the hospital ran entirely on paper and the digital services weren’t fully restored until 6 December.

Media reports, citing police sources, put the ransom demand at roughly ₹200 crore ($23–24 million), allegedly from LockBit, though no payment or attribution was ever confirmed. What is confirmed is that an estimated 30–40 million patient records were compromised. Delhi Police classified the case as cyberterrorism under Section 66F of the IT Act, and the CBI, NIA, Intelligence Bureau, and CERT-In all joined the probe, with jurisdiction itself a point of confusion.

The root cause was that the AIIMS systems hadn’t been meaningfully upgraded in decades along with the weak network segmentation due to which the 5 compromised servers took down the whole digital backbone. When AIIMS faced a second intrusion attempt in November 2023, the government confirmed no breach and no disruption thus proving that these attacks are survivable when checks are in place.

The SolarWinds Hack (United States, 2019–2020)

SolarWinds’ Orion platform is unglamorous network monitoring software used by roughly 33,000 organizations reflecting that it had privileged access deep inside their networks. Around September 2019, suspected hackers quietly entered SolarWinds’ own build environment. In February 2020, they inserted a backdoor SUNBURST into Orion’s source code before it was compiled and signed. Between March and June 2020, roughly 18,000 customers downloaded that legitimate, malware-laced update. It sat undetected until December 2020, when cybersecurity firm FireEye discovered its own breach traced back to a corrupted Orion update. Attackers had used the access to reach a smaller set of roughly 100–200 high value targets, reportedly including the US Treasury, State, Homeland Security, Commerce, Justice and the Energy departments plus the National Institutes of Health, Microsoft, Cisco, Intel and Deloitte.

Nothing was encrypted or ransomed, this was intelligence gathering, which makes the cost harder to tally but no less real. SolarWinds spent over $40 million in three months on remediation, paid $26 million to settle a shareholder lawsuit, and fought a 2 year SEC case naming its CISO for allegedly misleading investors. Some estimates put economy-wide cleanup costs as high as $100 billion. The deeper lesson, hackers didn’t breach 18,000 organizations one by one, they breached 1 trusted vendor and let its own signed update do the work, since standard practice wasn’t built to question a signed update from a known vendor.

What Each Stakeholder Should Take Away

CEOs and Board Members: AIIMS shows what happens when internal risk goes unexamined for years. SolarWinds shows a signed, trusted update can be the attack itself. Ask which vendors or systems could halt operations for two weeks, treat routine updates as verifiable and rehearse a prolonged outage before one happens for real.

Regulators: India had no data protection law when AIIMS was breached. The DPDP Act wasn’t notified until August 2023, with full enforcement not expected until 2027. The US moved faster, the executive order arrived within 6 months, mandating Zero Trust and SBOM requirements but the adoption has been uneven, and the SEC’s CISO case was ultimately dismissed. Even fast regulation can end up short on teeth.

The Public: AIIMS was directly disruptive — delayed labs, exposed diagnoses. SolarWinds was quieter, aimed at governments and corporations, not consumer data but it’s a reminder that software behind the institutions holding your health data can be compromised even when nothing looks wrong but is worth expecting real security discipline and not just a reassurance message.

Interested? Visit our website

Please note: The author of this blog is Shantanu Kohli, with inputs from Girish Elchuri & Rinka Singh.

ISPIRT Participation Technical Working Group (TWG-1) Stakeholder Consultation :Data Curation, Sharing & Governance | 6–7 July 2026 at IIT Bombay

As India advances toward an AI-enabled healthcare ecosystem, robust frameworks for data curation, sharing, and governance are essential to ensure that innovation is ethical, interoperable, privacy-preserving, and trusted. High-quality, discoverable, and reusable health data forms the foundation for responsible AI applications in healthcare, ranging from clinical decision support and population health management to medical research and personalized care.

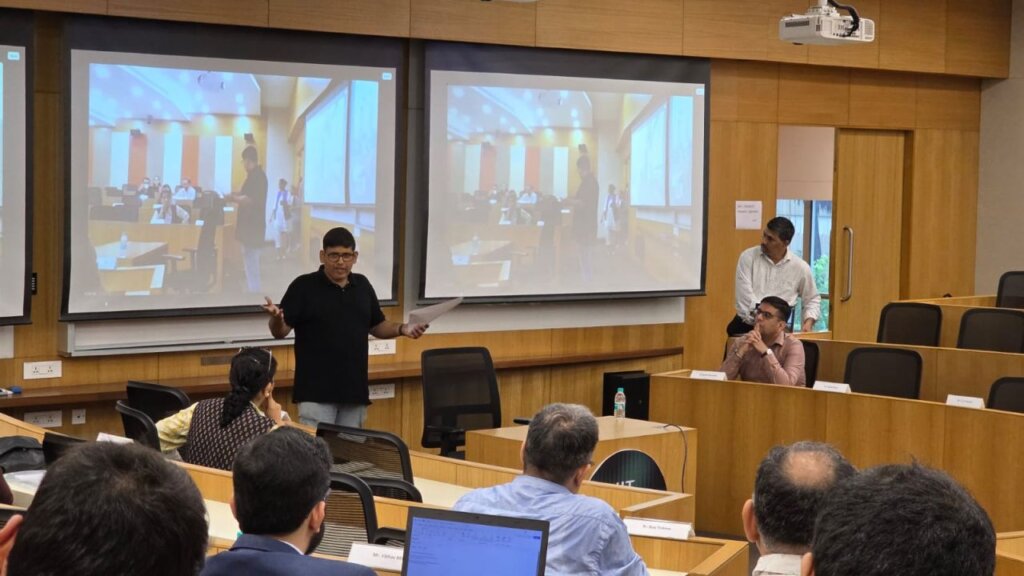
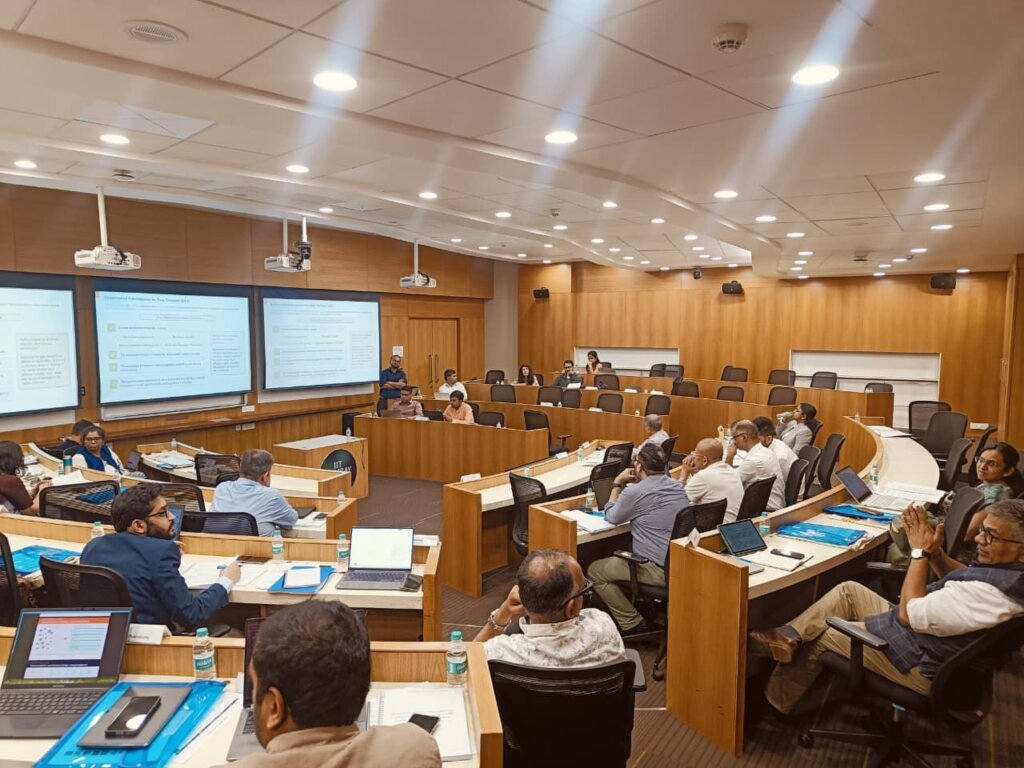
The ICMR–National Institute for Research in Digital Health, in collaboration with the Koita Centre for Digital Health (KCDH), IIT Bombay, successfully hosted the Technical Working Group (TWG-1) Stakeholder Consultation Write-Shop on Data Curation, Sharing & Governance on 6–7 July 2026 at IIT Bombay.

ISPIRT participated in the event as subject matter experts (Tags – Dr Shyam Sundaram & Shikhar Verma), contributing perspectives on data empowerment, approaches to data Collaboration using data blinding framework , and the role of digital public infrastructure in enabling an AI-ready healthcare ecosystem in the context of the technical working group related to Data Curation, Sharing & Governance

The workshop brought together leading experts from government, academia, healthcare, industry, and policy domains to collaboratively develop recommendations for strengthening India’s health data ecosystem. Through focused and highly interactive discussions, participants examined the full health data lifecycle, including data curation, governance, interoperability, ethical and legal considerations, data sharing and reuse, AI model governance, operational frameworks, and capability maturity. The consultation provided a valuable platform for aligning stakeholder perspectives and advancing a shared vision for a secure, interoperable, and AI-ready digital health ecosystem for India.

In this context, ISPIRT highlighted as a feedback the importance of Data Empowerment and Protection Architecture (DEPA) as a foundational framework for empowering responsible AI enabling secure data sharing for AI model training.

DEPA Private Inferencing

At iSPIRT, our work on digital public infrastructure for data has consistently focused on a core question: how do we unlock value of data while preserving the rights and trust of individuals? With DEPA (Data Empowerment and Protection Architecture), we established a consent-driven framework that empowers individuals to control how their data is shared for a specific purpose. But there are many business scenarios where consent alone is not sufficient.

Consider a simple scenario: a user consents to share their bank transaction data with multiple lenders for the purpose of credit underwriting. The consent artifact clearly specifies purpose, duration, and data scope. However, once that data is shared with the lenders, the user, and even the bank has no technical visibility into how exactly the data is being used by the lender. Are the lenders only computing a credit score, or also deriving behavioral insights for cross-selling? Are any of the lenders retaining longer than necessary? Is the data being combined with other datasets in ways that go beyond the original intent? These questions are becoming increasingly critical as the use of AI for processing personal data expands to pretty much every sphere from agriculture to finance and healthcare. Consent defines permission, but today there are no technical means to ensure that consent is respected.

DEPA Private Inferencing (part of DEPA 2.0) addresses these concerns. It is a framework that enables high-value scenarios, such as AI inference, while ensuring end-to-end, cryptographically verifiable privacy. DEPA Inferencing introduces a new paradigm: controlled data sharing within clean room environments. It allows data to be shared, but only within secure, purpose-limited and verifiable execution environments. This ensures that users’ consent is enforced while data consumers retain flexibility to run complex computations such as AI models while minimizing compliance costs.


✨ Highlights

👉 Unlocks cross-institution inference without exposing customer data to counterparties

👉 Today: 2 million+ private customer inferences in BFSI sector processed within 2 weeks

👉 Open-source stack available for ecosystem adoption and innovation


Before we dive in, let’s quickly recall what the Data Empowerment and Protection Architecture (DEPA 1.0) really is.

What is DEPA and why does it matter?

India Stack is evolving at population scale, enabling the flow of people (Aadhaar, eKYC, DigiLocker, DigiYatra, etc), money (UPI, OCEN), and information (DEPA and Account Aggregator) through Digital Public Infrastructure (DPI). DEPA is foundational to this third layer. It enables the responsible flow and use of data between individuals and organisations for higher-order economic activity such as cross-sell, analytics, AI model training, and AI inference.

As the name suggests, DEPA rests on two key elements. The first is protection, founded on the bedrock of privacy, consent, accountability and purpose limitation of data. The second is empowerment, democratizing data access and enabling the ecosystem to responsibly innovate with it, whether for training AI models, personalizing products and services, advancing scientific research, and a lot more.

The first instantiation of DEPA is the Account Aggregator (AA) framework, which enables real-time user-consented data sharing between Financial Information Providers (FIPs), entities who hold citizen data, and Financial Information Users (FIUs) or entities that require citizen data to provide a service. That model has been transformative for many use cases and remains foundational to India’s data ecosystem.

What is DEPA Private Inferencing?

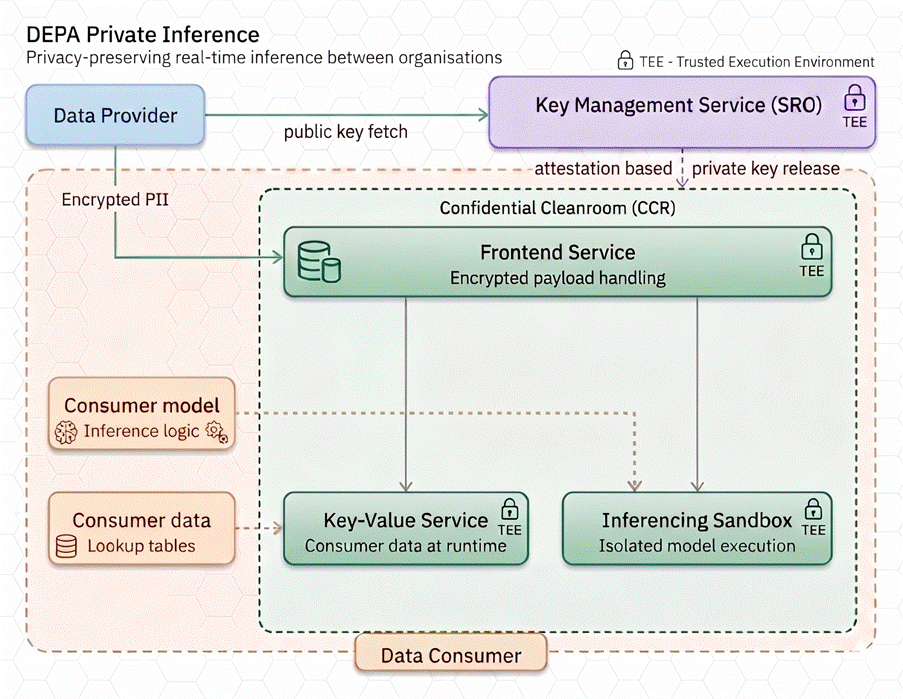
DEPA Private Inferencing builds on this foundation by introducing a new layer of control at the point of computation. Instead of transferring data to the consumer’s environment, data is released into a Confidential Clean Room (CCR), a hardware-based secure execution environment where computation happens under strict policy enforcement.

In this model, a data provider (DP) allows access to relevant data to a data consumer (DC), governed by user consent (obtained using AA or otherwise). However, instead of getting raw access to the user’s data, the data consumer (DC) brings their inference logic (for example, a credit risk model) into a confidential clean room. The clean room itself enforces constraints on what data can be accessed, how it can be processed, and what outputs can be generated.

In the first incarnation, DEPA Private Inferencing supports a clean room environment that allows the data to be enriched using the PDC’s own data hosted in the clean room followed by inference using the PDC’s AI model. During this process, the clean room environment ensures that

a) personal data remains encrypted at all times, even during use,

b) inferencing is stateless i.e., the AI model cannot keep any state once the data has been processed, and

c) only the results of inference in a predetermined format are returned to the DP.

Importantly the clean room environment ensures that the DC (or for that matter the cloud provider) cannot observe or tamper with the data or the computation, even if the DC is hosting this computation. This is a subtle but important shift. Data does move, but only into an environment where its usage is technically controlled and purpose limited, even from the DC.

DEPA Private Inferencing provides these assurances using confidential computing, a new set of primitives in modern CPUs (Intel, AMD and ARM) and GPUs (from NVIDIA) which enable creation of cryptographically verifiable isolated execution environments called Trusted Execution Environments (TEEs). TEEs ensure that data remains protected throughout its lifetime, at rest, in transit, and during use. TEEs are now broadly available on most cloud platforms and have been battle-tested in large scale deployments such as WhatsApp and Signal.

If the confidential clean room is where trust is enforced, key management is what ensures that this trust cannot be bypassed. In DEPA Private Inferencing, keys for encrypting data as it is transferred from the DP to the DC are generated and governed within a dedicated, transparent key management service (KMS) operated by Samyog, a neutral not-for-profit self regulated organization (SRO) set up for this purpose. Access to private keys is tightly coupled with attestation. Personal data is encrypted using public keys from the KMS. However, before an inferencing service hosted by a PDC can decrypt data, it must prove, using hardware-backed attestation, that it is running clean room code approved by Samyog inside a genuine TEE. Only after this verification does the KMS release the required decryption key securely wrapped so it can only be used within that specific clean room environment. This creates a separation of control, ensuring that no single participant in the ecosystem can unilaterally access sensitive data.

Similar to the clean room, the KMS itself runs within a tamper-evident, fault-tolerant TEE, with transparency and auditability over key release policies, ensuring even administrators of the KMS cannot access private keys.

DEPA Private Inferencing in action

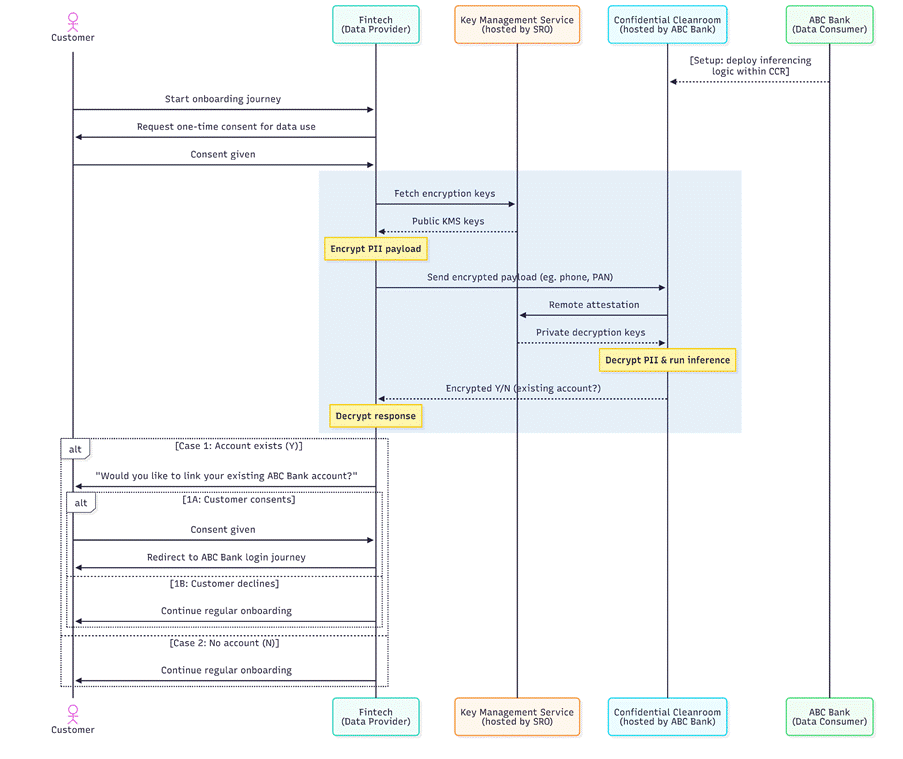
Our first production deployment of DEPA Private Inferencing connects a leading commercial bank (Data Consumer) with a regulated fintech (Data Provider) to run a simple private inference: Does this fintech customer already hold an account at the bank?

Once the DPDP Act is operationalized, even answering this simple question today will be challenging, because as soon as the customer’s data (e.g., mobile number and PAN card) is exposed to the bank, the bank is responsible for managing the entire consent and data lifecycle. Given banks today typically integrate with dozens of such partners, this creates significant operational and compliance overhead.

With DEPA Private Inferencing, the bank can receive this data in encrypted form inside a CCR pre-loaded with its own customer information, process it, and generate a yes/no response – while proving to the fintech partner that the data was used only for this specific purpose, and that the bank has no technical means to access or retain this data. This builds trust, reduces exposure of raw data, and significantly simplifies partner integrations at scale.

Already, within the first two weeks of deployment, DEPA Private Inferencing has processed over 2 million cross-institution inferences, with a p99 latency of < 100ms, while meeting all of the bank’s security and compliance requirements.

Figure: Example Private Inference flow between a Fintech and a Bank.

A New Primitive for the Data Economy

DEPA Private Inferencing represents a shift from thinking about data as something that must be transferred, to thinking about computation as something that can be safely hosted. The clean room becomes the unit of trust, a neutral, enforceable space where data and algorithms interact under well-defined constraints. As India’s digital public infrastructure continues to evolve, this approach lays the groundwork for a more trustworthy and scalable data economy, one where innovation does not come at the cost of control, and where consent is not just captured, but meaningfully upheld.

Get started

👉 Dive into the code: DEPA‑Inferencing on GitHub 🛠️
👉 Reach out to [email protected] for more info.
👉 Watch the Open House video: YouTube 🎬

👉 Think big: What challenges has data privacy kept off-limits? What data has felt forever inaccessible? With DEPA, those doors may finally open. 💡

Interested in contributing to DEPA? Join our group of no-greed no-glory volunteers! Apply here

SAKRAM: A Practice

For a long time, cybersecurity was seen as a defensive measure used to block threats, fulfill compliance requirements and was considered a burdensome cost to be handled by the IT team alone. As technology has evolved, so has our perspective. Today, cybersecurity plays a direct role in driving business growth, ensuring operational continuity and building long term resilience. The questions organizations ask have changed as well. Instead of focusing only on how to prevent breaches, businesses now ask how to stay operational, recover quickly and maintain trust when incidents happen. This reflects an important shift from seeing cybersecurity as a simple protection measure to recognizing it as a foundation for resilience. 

Whether you’re running an IT services company, a financial institution, a manufacturing unit or a startup, your business runs on digital infrastructure. Data, applications, and platforms are now core business assets and when these are at risk, your entire business is at risk. This means cybersecurity can’t remain confined to the IT department. It needs to align with your business strategy, executive decisions, operational planning, and customer expectations. 

In cybersecurity, risk never disappears, it only changes owners. A strong cybersecurity strategy rests on 5 pillars that work together to build organizational resilience: 

  1. Governance & Leadership: When leadership is committed, cybersecurity becomes part of a company’s culture rather than just a technical concern. 
  2. Risk Management & Assessment: Regular assessments help identify critical assets, vulnerabilities, and potential impacts. Understanding what needs the most protection helps you allocate resources efficiently. 
  3. Incident Response & Recovery Planning: Even strong defenses can fail. A well tested incident response and recovery plan ensures quick detection, containment, and recovery while minimizing downtime and damage. 
  4. Employee Awareness & Training: Human error is still a leading cause of breaches. Regular training transforms employees
  5. Continuous Improvement & Adaptation: Threats evolve daily, so your defenses must adapt too. Cybersecurity is an ongoing journey of learning, testing, and improvement.

An effective cybersecurity program requires continuous focus and adaptation from every department and individual in the organization, becoming an ongoing practice rather than a one time project that works in loops to address alerts, issues, vulnerabilities, and changes as they happen.

At iSPIRT, SAKRAM is our proposed solution to comprehensively deal with cybersecurity threats. It is a comprehensive practice designed to help organizations strengthen their cybersecurity defenses and protect their digital assets, along with those of their partners and customers. It is built on the principle of continuous execution, facilitating what we call an “Always Secure” system. Over the coming weeks, we will be publishing a dedicated series of blogs (and videos) that unpack SAKRAM in depth: what it is, how it works and how your organization can put it into practice. Each piece will build on the last, giving you both the strategic picture and the practical tools to act on it.

Note: This is the first part of a multi-part blog series.

Interested? Visit our website

Please note: The author of this blog is Shantanu Kohli, with inputs from Girish Elchuri & Rinka Singh.

Broadening Credit Access: The Quiet Evolution of OCEN

Financial ecosystems are rarely transformed overnight. Instead, they evolve through the steady
alignment of technology, policy, and trust. Over the past year, the Open Credit Enablement
Network (OCEN) has been moving quietly in this direction, acting as a digital bridge between
credit-starved MSMEs and a diverse pool of lenders.
The Growth Narrative: In Q1-2025, the network facilitated 5,641 loans totaling 19,795 Lacs.
Fast forward to Q1-2026, and the momentum has scaled to 35,485 loans with a disbursement
value of 112,484 Lacs. This represents a 468% surge in disbursement value—a testament not to
the protocol alone, but to the readiness of the Indian MSME to embrace digital, cash-flow-based
credit.

Strengthening the Foundation

Beyond the numbers, the structural progress of the ecosystem offers a glimpse into a more
inclusive future. Today, six diverse lenders—ranging from large Public Sector Undertakings
(PSUs) to agile NBFCs—are live on GeM Sahay and many others in the process of integration.
This diversity ensures that credit is not a ‘one-size-fits-all’ product but is tailored to the risk
appetite and specific needs of the borrower.
The horizon is also widening. We are currently piloting programs for Non-Sole Proprietors on
GeM Sahay, significantly expanding the eligible borrower base. Furthermore, MSME suppliers to
the CGDA can now avail finance against Purchase Orders via GeM Sahay, marking a critical step
in supporting those who serve our national interests.

The Quality of Growth

A frequent concern in rapid credit expansion is delinquency. However, OCEN’s emphasis on
cash-flow-based lending rather than traditional asset-based collateral has yielded encouraging
results. To date, lenders have observed negligibly low delinquency across programs, proving that
data-backed lending to the ‘unbanked’ is not just a social imperative, but a sound financial
strategy.

Looking Ahead: An Invitation to the Ecosystem

The journey has only just begun. We are actively developing programs that touch every corner of
the economy:

  • Micro-MSMEs: Providing vital credit to the gig economy and individual workers.
  • Agri & Dairy: Strengthening the backbone of rural commerce through value-chain
    financing.
  • Digital Sellers: Empowering e-commerce marketplace sellers and MSMEs using modern
    ERP/Accounting software.
  • Regional Clusters: Addressing the unique needs of localized industrial hubs.

For lenders, platforms, and technology providers, OCEN represents a unique opportunity to
participate in a high-growth, low-friction credit market. As we move forward, we remain
committed to a humble approach—learning from the data, listening to our partners, and ensuring
that every disbursed Rupee contributes to the broader story of India’s economic resilience.

OCEN: Empowering Growth, One Transaction at a Time.

For more information, please visit: http://ocen.dev

Please note: The blog post is authored by our volunteer, Rahul Bhaik

DEPA-Training: Tech Updates

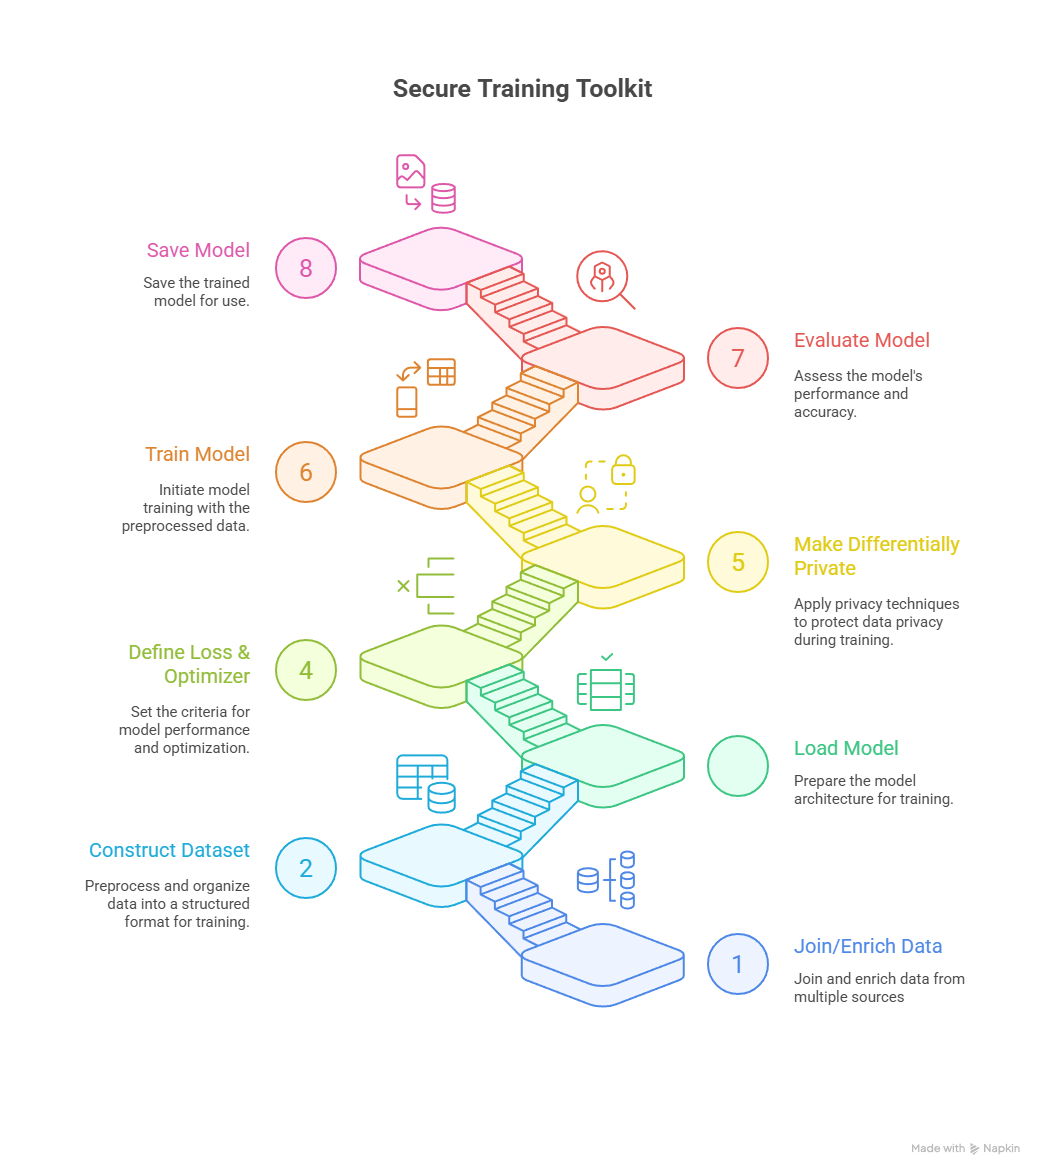
We’ve rolled out some exciting updates for DEPA‑Training, making it easier to rapidly prototype and run diverse training scenarios — complete with electronic contracts, confidential cleanrooms, privacy-preservation and configurable training SDKs.


✨ What’s new

👉 GUI for end-to-end execution

👉 Step-by-step guide to create and run your own training scenarios

👉 New scenarios introduced for complex multi-party training: MRI brain tumor segmentation, credit default risk prediction


Before we dive in, let’s quickly recall what the Data Empowerment and Protection Architecture (DEPA) really is.

What is DEPA and why does it matter?

India Stack is evolving at population scale, enabling the flow of people (Aadhaar, eKYC, DigiLocker, DigiYatra, etc), money (UPI, OCEN), and information (DEPA and Account Aggregator) through Digital Public Infrastructure (DPI). DEPA is critical in this third layer as it enables the responsible flow of data between individuals and organisations for more complex tasks such as AI model training, AI inference and analytics. 

As the name suggests, DEPA rests on two key elements. The first is protection, founded on the bedrock of privacy, consent, accountability and purpose limitation of data. The second is empowerment, democratizing data access and enabling the ecosystem to responsibly innovate with it, whether for training AI models, personalizing products and services, advancing scientific research, and a lot more.

In light of emerging data protection laws such as the DPDP, GDPR, and others, there is a need for a framework that enables the responsible use of data — unlocking its value while ensuring regulatory compliance and serving the broader public interest.

Ultimately, DEPA solves for two core challenges at the heart of data sharing — Trust and Flow — keeping the rest open and flexible for innovation.

What is DEPA‑Training?

The vision behind DEPA for Training (aka DEPA‑Training) is simple: For India to not only be a consumer of AI, but also a producer of AI, and in a responsible and democratized manner.

AI’s first big leap came from public data. That well is running dry. Our belief is that for the next wave of AI innovation — smarter AI for healthcare, personalized finance, scientific discovery and more — proprietary data will be crucial. But today, that data is fragmented, locked in silos, and difficult to use — often running into challenges around privacy, compliance, and regulatory constraints.

Enter DEPA-Training — a techno-legal Digital Public Infrastructure (DPI) designed to enable secure, agile, and scalable AI model training on sensitive data. It does so by assembling a set of frontier technological primitives:

  • Confidential Clean Rooms (CCRs): Isolated compute environments that can cryptographically attest to their integrity, where data can be processed securely without external exposure.
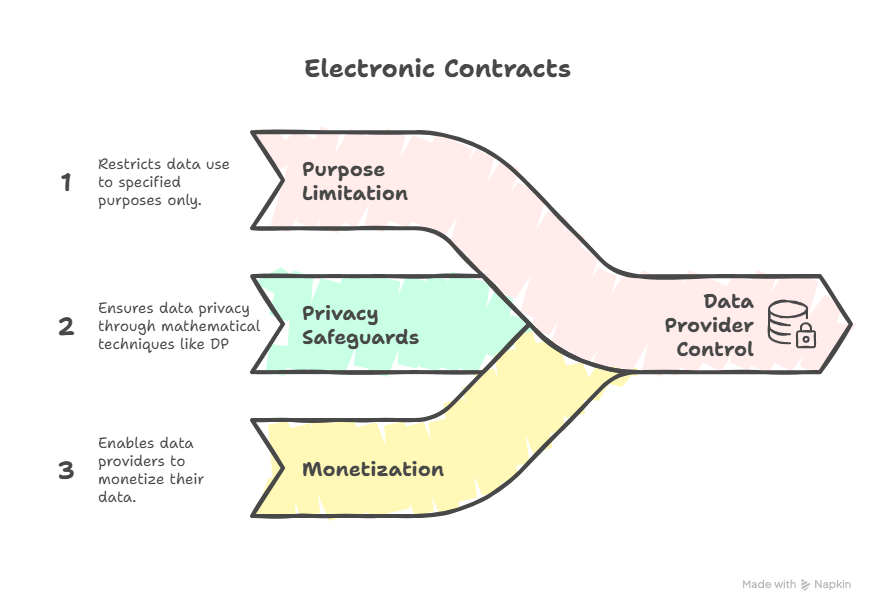
  • Electronic Contracts: Code-enforced legal agreements between transacting parties, that give data providers control over how their data is used, for eg. through purpose limitation, privacy safeguards and monetization.
  • Secure Training Sandbox: Modular and configurable sandboxes and SDKs for building privacy-preserving and compliant training pipelines across diverse model architectures and data types.

What’s new in DEPA-Training?

Graphical user interface

We’ve introduced an interactive GUI that enables users to explore, configure, and execute DEPA-Training scenarios end to end. The application automatically discovers available scenarios in the repository and provides an intuitive interface to run them — eliminating the need for command-line interaction. A similar GUI workflow is also provided for contract signing.

Scenarios you can try out today

To bring DEPA-Training to life, we showcase a diverse set of scenarios that demonstrate what’s possible in practice. These examples illustrate pathways toward solving larger global challenges and span multiple data modalities (e.g., tabular, images), model paradigms (e.g., classical ML, MLPs, CNNs), and prediction tasks (e.g., regression, classification, image segmentation).

Disease Surveillance Modeling

Pandemics don’t wait. Timely, accurate data can save millions of lives. Yet most infection data is scattered, siloed, and too sensitive to share. With differential privacy, institutions can securely pool data to track virus spread, map risk patterns, and test interventions — powering real-time, data-driven epidemic response.

Example: COVID-19 scenario

Medical Image Modeling

From cancer to cardiovascular disease, from neurology to rare disorders — modern medicine increasingly depends on imaging. Yet medical images are among the hardest datasets to share, trapped in hospital silos and governed by strict privacy laws. DEPA makes it possible to combine imaging data across borders and institutions, unlocking AI models that are more accurate, generalizable, and equitable. This accelerates breakthroughs in diagnostics, improves treatment planning, and addresses one of healthcare’s biggest global challenges: scaling precision medicine while safeguarding patient trust.

Example: BraTS scenario 

Financial Credit Risk Modeling

Access to fair credit fuels economic growth, but risk assessment is often limited by partial data. By safely combining insights across financial institutions, DEPA enables more accurate credit scoring, reduces defaults, and strengthens financial stability — empowering individuals and businesses alike with better access to capital.

Example: Credit Risk scenario

Build your own Scenarios

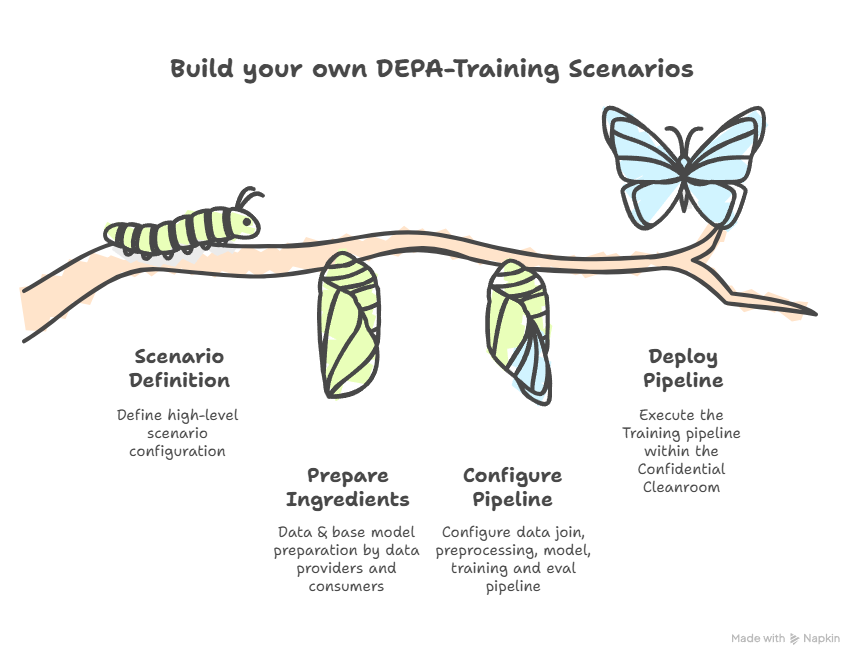
A new step-by-step guide walks you through building and running your own DEPA-Training scenarios — making it easy to rapidly prototype and iterate with training use-cases of your own.

Currently, DEPA-Training supports the following training frameworks, libraries and file formats (more will be included soon):

  • Frameworks: PyTorch, Scikit‑Learn, XGBoost (LLM Finetuning to be added soon!)
  • Libraries: Opacus, PySpark, Pandas (HuggingFace support coming soon!)
  • Formats: ONNX, Safetensors, Parquet, CSV, HDF5, PNG (No pickle-based formats for security reasons)

What’s in it for the ecosystem?

DEPA-Training democratizes responsible data sharing and model training for all!

  • Enterprises & Startups → Unlock the value of private data to build smarter products and services, while remaining compliant to data laws. Collaborate across organizations to create solutions that no single dataset could power.
  • Research Institutions → Pool data at scale to tackle grand challenges, drive scientific discovery, and advance knowledge for the public good.
  • Policy & Legal Experts → Shape the future of data governance by operationalizing privacy, consent, purpose limitation, and accountability in practice.
  • Builders & researchers → Join us in co-creating this framework!

Get started

👉 Get your hands dirty: DEPA‑Training on GitHub 🛠️

👉 Explore the documentation: DEPA.World 📜
👉 Watch the Open Houses: YouTube Playlist 🎬

👉 Think big: What challenges has data privacy kept off-limits? What data has felt forever inaccessible? With DEPA-Training, those doors may finally open. 💡

Interested in contributing to DEPA? Join our group of no-greed no-glory volunteers! Apply here

Please note: The blog post is authored by our volunteers, Sarang Galada, Dr. Shyam Sundaram, Kapil Vaswani and Pavan kumar Adukuri

A Budget that missed the opportunity for being bold on both Strategic Autonomy & Reform action

 iSPIRT Foundation, a technology think-and-do tank, believes India’s hard problems can be solved only by leveraging public technology for private innovation. iSPIRT, as a think-and-do-tank, pioneered the concept of Digital Public Infrastructure (DPI)

The Budget starts by acknowledging that India is facing “an external environment in which trade and multilateralism are imperilled and access to resources and supply chains are disrupted”. But the details aren’t in line with the idea. The Government also acknowledged AI and cutting-edge technologies as force multipliers for better governance. 

AI has been spoken about a few times at different places. However, there is no material proposal on AI, except as a tool for “Bharat-VISTAAR”—a multilingual AI tool in agriculture.

FM announced Manufacturing support to seven strategic and frontier sectors, including Bio-Pharma, Chemicals, Semiconductors, and Electronic Components. This will help the ecosystem build up in these sectors and, in a way, support the cause of “Product Nation” from a building capacity and infrastructure point of view. However, it does not address “strategic autonomy” and technological sovereignty as a thought process. 

The one that most closely links to “Aatmnirbhar Bharat” or strategic autonomy is the announcement on ISM 2.0, to produce equipment and materials, design full-stack Indian IP, and fortify supply chains, including skilling and training. Also, the mention of established dedicated Rare Earth Corridors is a welcome move to fill the gaps in the supply chain in these areas, given the geopolitical situations. 

Any Government announcement takes about 2 years to roll out in the field. The AI Mission, National Quantum Mission, Anusandhan National Research Fund, and Research and Development and Innovation Fund have been mentioned by the FM in speech. RDI is rolling out now. The government missed the bus to announce a “market access” scheme or a fund for the products developed after taking all the steps in R&D and frontier technology advancements. 

We have maintained that our Economic Policy will need to foreground Strategic Autonomy as a core pillar, which becomes all the more imperative in the current global geopolitical scenario. But Strategic Autonomy is not possible without technological sovereignty. While the government has taken steps to “reduce critical import dependencies,” at a time when “new technologies are transforming production systems”, incremental steps are not enough.

“A market access plan for Indian products designed and developed in India by resident Indian companies is the need of the hour for any fruitful outcome from R&D and product development. The Government must consider this with all seriousness in the future,” said Amit Agrahari, volunteer at iSPIRT Foundation.

Last year, Bharat Trade Net was announced as an integrated trading platform. This year’s announcement of “Customs Integrated System (CIS) as a single, integrated and scalable platform for all the customs processes and use of non-intrusive scanning with advanced imaging and AI technology for risk assessment, takes the thought to the next level.  This is very much in line with our National Regulatory Compliance Grid (NRCG) approach and use of advanced technology for data-driven governance. 

However, our proposal of building a NRCG for all regulatory systems is still waiting. “Unless we use a Grid approach for digital transformation and connect all regulators, it is going to be difficult to reduce the regulatory cholesterol”, said Sudhir Singh, an iSPIRT Volunteer looking after Ease of Doing Business, and Policy. 

Linking TreDS with the GeM portal is a welcome step towards unlocking true Digital potential in Ease of Doing Business for MSMEs. “This can further create a grid approach by connecting to the Open Credit Enablement Network (OCEN) and trade finances for SME exporters,” said Tanuvi Thakur, volunteer at iSPIRT Foundation. This will further aid EoDB through quicker and cheaper access to credit by MSMEs. 

The other major welcome step in this regard has been the in-principle movement from penalty and prosecution to fees. This has also been our core decriminalisation aim for achieving EoDB.

Overall, it’s a subdued Budget despite the challenging geopolitical environment rather than a bold Budget that speaks on both “strategic autonomy” and “reforms”.

About iSPIRT Foundation – We are a non-profit think-and-do tank that builds public goods for Indian product startups to thrive and grow. iSPIRT aims to do what DARPA or Stanford University did in Silicon Valley for startups. iSPIRT builds four types of public goods – technology building blocks (aka India Stack), startup-friendly policies, market access programs like M&A Connect, and Playbooks that codify scarce tacit knowledge for product entrepreneurs of India. For more, visit www.ispirt.in.

For further queries, please reach out via email:  [email protected], [email protected] 

Please note: The blog post is authored by our volunteers, Sudhir Singh, Tanuvi Thakur and Amit Agrahari

OCEN 2025

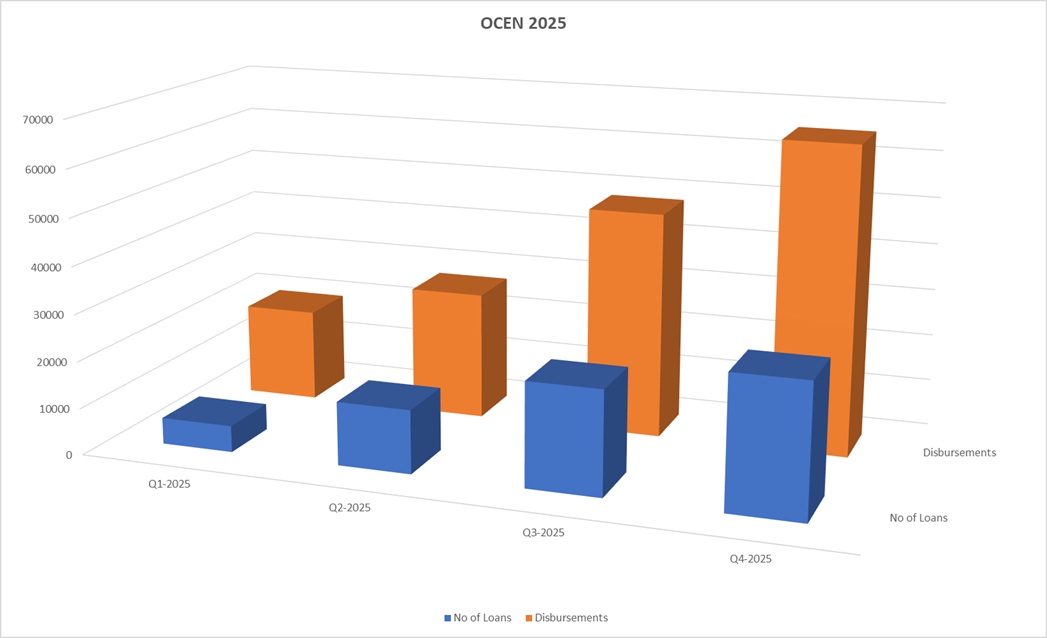
The calendar year 2025 has been a transformative period for the Open Credit Enablement Network (OCEN), evolving from a digital protocol into a powerhouse for financial inclusion. During 2025, OCEN successfully facilitated approximately 70,000 loans, resulting in over ₹1,600 Crore in disbursements.

This journey is not just about the numbers; it is about proving that a digital-first, cash-flow-based approach can solve the long-standing credit gap for underserved MSMEs with unparalleled efficiency.

A Year of Relentless Monthly Momentum

The 2025 journey began with a steady climb and rapidly escalated as more lenders and borrower agents integrated into the ecosystem. The monthly growth in the number of loans disbursed showcases a consistent upward trajectory. This steady monthly rise provided the foundation for the explosive quarterly growth that defined the year.

Consistent Quarterly Growth (QoQ)

When looking at the 2025 performance on a quarterly basis, the scale of adoption becomes even more evident. The network didn’t just grow; it accelerated every three months.

Period (2025)No. of LoansDisbursements (₹ Lakhs)
Quarter 15,64119,795
Quarter 213,51627,316
Quarter 322,14248,092
Quarter 428,12265,275

The jump from Q1 (5,641 loans) to Q4 (28,122 loans) represents an increase of nearly 400% in loan volume within a single year. Similarly, disbursements surged from ₹197.9 Crore in Q1 to over ₹652.7 Crore in Q4, demonstrating the massive appetite for small-ticket, short-tenure credit.

Portfolio Quality: The Ultimate Validator

The most significant achievement of 2025 isn’t just the volume—it’s the quality of the credit. Traditional MSME lending often suffers from high risk and significant non-performing assets (NPAs). OCEN has fundamentally challenged this narrative.

Participating lenders have seen highly encouraging results in portfolio health, characterized by strong performance, minimal portfolio losses and high confidence. The cash-flow-based underwriting model allows lenders to assess real-time business health rather than relying on stale collateral documents. Data-driven, short-tenure lending ensures high repayment rates.

The Future is Cash-Flow Based

OCEN’s 2025 journey proves that when you align technology with the actual business cycles of small enterprises, everyone wins. MSMEs get the “just-in-time” capital they need, and lenders gain access to a high-quality, low-risk asset class. With over ₹1,600 Crore disbursed in 2025, the protocol has set a new benchmark for how India can democratize credit and fuel the next wave of economic growth.

For more information, please visit: http://ocen.dev

Please note: The blog post is authored by our volunteer, Rahul Bhaik

OCEN Crosses the ₹200 Crore Monthly Milestone: Redefining MSME Credit Quality

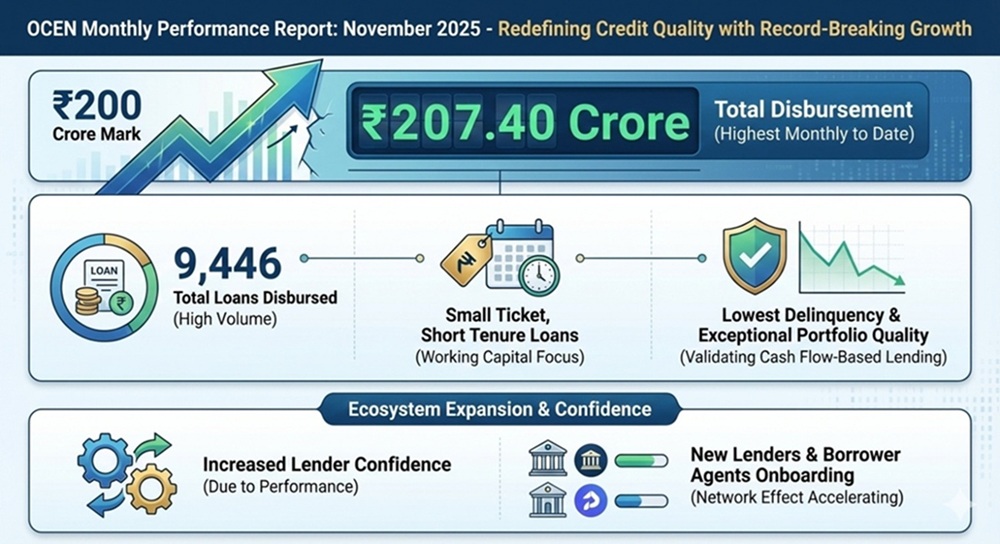
November 2025 has officially set a new standard for the future of cash flow based digital lending for MSMEs in India. For the first time, monthly disbursements through the OCEN protocol have breached the ₹200 Crore mark, proving that the shift toward cash flow-based lending is not just a pilot—it is a powerhouse.

As we move toward the close of 2025, the narrative is shifting from “how much” can be lent to “how well” it is being managed.

November 2025: By the Numbers

The growth trajectory of OCEN continues to follow a healthy curve. The protocol recorded its highest disbursement month to date, characterized by high-velocity, small-ticket lending that reaches the very grassroots of the MSME sector.

  • Total Disbursement: ₹207.40 Crore
  • Total Loans Disbursed: 9,446
  • Primary Loan Profile: Short-tenure, small-ticket working capital

This monthly performance brings the total calendar year disbursement to new heights, reinforcing OCEN’s role as an important digital highway for reducing the MSME credit gap.

The Quality Paradox: High Growth, Lowest Delinquency

In traditional lending, rapid growth often comes at the cost of asset quality. OCEN is turning this logic on its head. Despite the surge in volume, the participating lenders are reporting the lowest delinquency rates in the MSME segment.

The loan portfolio performance on OCEN has been exceptionally better than traditional MSME lending portfolios, which often struggle with high NPAs due to delayed data and static underwriting. By leveraging cash flow transaction data, OCEN allows for precision underwriting enabling the lenders see the actual health of a business today, not six months ago. As the Lenders focus on underwriting a Cash flow transaction rather than underwriting a borrower, the Short-tenure loans ensure that capital is cycled quickly linked to the Cash flow being financed, reducing long-term exposure risk.

This “quality-first” growth has sparked a wave of confidence across the participating lenders. We are currently seeing multiple new lenders and borrower agents at various stages of onboarding onto the OCEN framework. As more entities join, the network effect will only intensify, making credit even more affordable and accessible for the millions of “Rajnis” running small shops and enterprises across India. OCEN is not just lending money; it is building a system of trust where verified data, not just collateral, becomes the currency for growth.

For more information, please visit: http://ocen.dev

Please note: The blog post is authored by our volunteer, Rahul Bhaik

India’s silent Credit Revolution: OCEN Surpasses 50,000 Loans and ₹1100 Crore in 2025

The Micro, Small, and Medium Enterprises (MSME) sector is the engine of the Indian economy, yet for years, it has been choked by a massive credit gap. Traditional, collateral-heavy lending processes simply could not keep pace with the dynamic, short-tenure funding needs of small businesses.

Open Credit Enablement Network (OCEN): Built on the principles of India Stack, this digital protocol is not just facilitating loans; it is fundamentally rewiring the architecture of MSME credit, making it instant, affordable, and accessible. The monthly growth witnessed in the calendar year 2025 proves the model is not just viable, but highly scalable, marking a new era of financial inclusion.

The Power of Cash Flow-Based Lending

OCEN’s disruptive approach lies in shifting the lending paradigm from asset-based to cash flow-based underwriting. For millions of creditworthy small businesses, their true financial health is reflected in their daily or monthly transactions, not in static, year-old balance sheets. By leveraging India’s digital public infrastructure, OCEN allows lenders to assess risk based on real-time, consented data helping them to take faster decisions and making small-ticket, short-tenure credit economically feasible for lenders.

This framework is specifically designed to solve for the underserved, those who need smaller loans for shorter periods but have previously been locked out of formal credit channels.

Demonstrating Growth and Inclusion

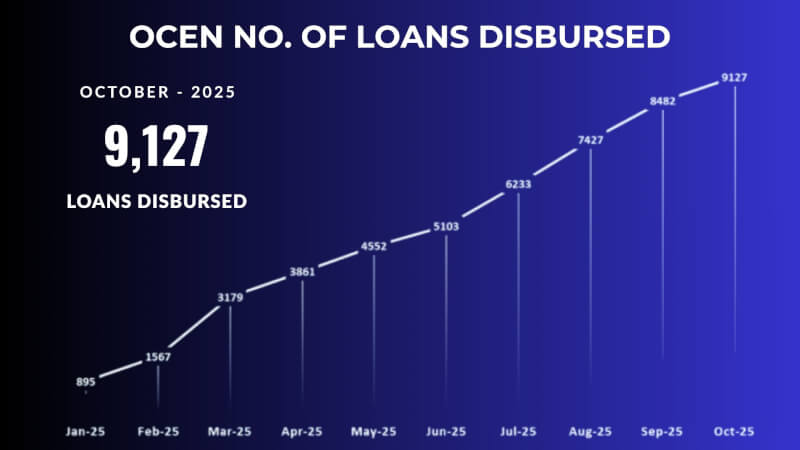
OCEN demonstrated its ability to deliver on its promise of democratizing credit. The network has disbursed 50,426 loans and amounting to ₹1142 Crore in total disbursement within the calendar year till October 2025.

October 2025: OCEN saw the highest ever monthly disbursement of 191 Crore across 9127 loans Catering directly to the daily needs of MSMEs. The growth highlights how the protocol’s architecture is perfectly suited for mass-market financial inclusion. The emphasis is clearly on the number of lives touched and the frequency of credit access, rather than just the size of the total loan book.

Validating the Model: Exceptional Portfolio Health

The true testament to OCEN’s cash flow-based underwriting is not just the speed and volume of disbursement, but the quality of the loan book. Crucially, the loans disbursed through the OCEN protocol have demonstrated very minimal Non-Performing Assets (NPAs). This performance is exceptionally better than the NPA figures typically observed in traditional MSME lending portfolios across the industry. This is not just a marginal improvement; it is a fundamental validation of the protocol’s ability to accurately identify and price risk among digitally visible, cash flow-rich MSMEs. By moving beyond outdated collateral requirements and relying on real-time transactional data,

OCEN is proving that digital, embedded credit is inherently safer and more sustainable than conventional lending practices, offering a high-growth, low-risk opportunity for participating lenders.

For more information, please visit: http://ocen.dev

Please note: The blog post is authored by our volunteer, Rahul Bhaik